
Running a Lab of Disposable Agents
Sixty-four agent branches, 212 commits and about sixty hours, run as one orchestrator handing single-purpose briefs to agents that never talked to each other. What acceptance bars and stop rules written in advance actually bought, what three identical stalls cost, and the round where an agent caught a false claim in my own lab log by diffing the prose against the code.
I own exactly one pole-dance motion-capture take. Thirty seconds, one performer, bought outright. Around it I built a system that extracts what I call the essence of the performance: a semantic contact script saying which hand grips the pole in which height band over which span of time, which foot is planted, which leg wraps, plus style curves for the manner of moving between those facts. Three target bodies with quite different proportions (ch33, ch02 and medea) then solve their own motion against that contract instead of wearing the source performer's copied joint rotations, which is what classical retargeting hands you. The hard part was legs passing through the pole, and a campaign to kill that defect class is the setting here. But this post is about how the campaign was run, not what it found, because the process turned out to be more portable than any of the fixes.
The shape of it
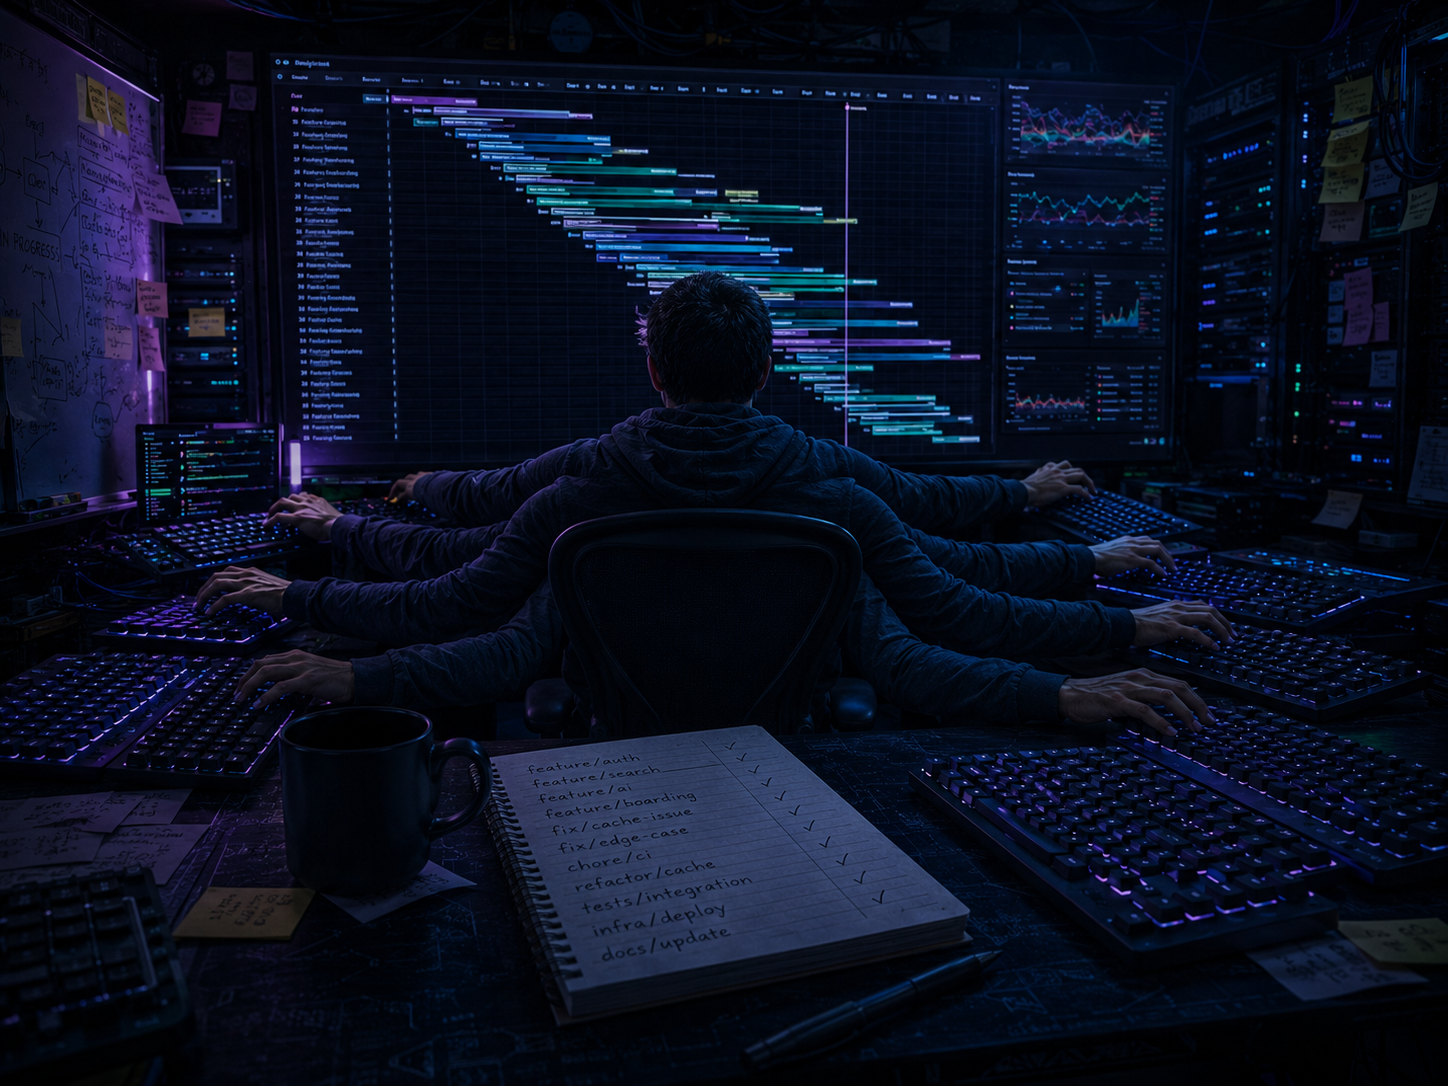
One orchestrator, one integration branch (essence-lab), and one worktree per agent. Sixty-four agent branches came off that trunk between the first campaign commit on 2026-07-24 at 12:05 and the close commit on 2026-07-27 at 00:27, about sixty hours of wall clock. Two hundred and twelve commits landed on the trunk, thirty-eight of them merges. The lab log (NOTES.md) ran to 16,754 lines by the end, and every one of those branches has a task log in it, with its own numbers.
Sixty-four branch swimlanes form a near-continuous staircase across sixty hours. Eight branches ended in a measured negative and were frozen default-off.
Every branch above is drawn from the repo rather than the log. The staircase is the orchestration: one round at a time, each starting about where the last finished. The measured negatives all sit in the final third, where the diagnosis work happened.
Agents did not talk to each other. They talked to the log. A task got a brief, a worktree, a file-ownership list and an acceptance bar, and wrote one entry when it was done. The orchestrator merged, re-verified, and wrote the next brief. That is the whole architecture.
The model split was written into the roadmap before any of it started: cheap agents for every implementation task, an expensive one only for cross-cutting diagnosis or a task that had already failed twice, and the orchestrator reserved for writing briefs, making gate calls with me, and post-mortems, with an explicit target of no orchestrator tool loops inside implementation work. How closely that held I only partly recorded. One overnight run is logged as nine tasks merged, all on the cheap tier.
I should be clear that this ran on a flat Claude subscription, not metered API access, so there is no per-task dollar figure to report and the tiering was never a cost optimization. What it bought, as best I can tell, was speed. I never timed a task, so that is an impression from running the thing rather than a measurement, and there is no serial baseline to compare it against: nobody ran this campaign the slow way. The impression is that a cheap agent turns a well-specified brief around fast enough that you can afford to spend one on a question you expect to answer no, which is most of what this campaign did.
Parallelism was bounded by file ownership, not by politeness. One task log opens by naming the four other agents working in parallel on adjacent slots and listing exactly which two files it owned. Another needed a one-line change in a shared library four agents were inside, and instead reproduced the function locally, minus the branch it wanted gone, importing the same constants so at least the numbers could not drift apart. That is a weaker guarantee than it reads as: shared constants do not keep two copies of a function semantically in step, and a later fix landing in only one of them is exactly the bill this defers. A third declined an optimization outright: fifteen-odd scattered edits across a 2,500-line span four other agents were concurrently editing, where a missed edit yields a wrong bake rather than a crash.
Briefs before work, and two keys
Every brief carried its acceptance numbers, its forbidden moves, and its exit condition before the agent started. The exit condition was almost always two strikes: two genuine, distinct attempts at one sub-problem with no measured improvement stops the task and requires a written bound instead of a third attempt. That fired at least seven separate times, and every time the failed attempt stayed in the tree behind a default-off flag with its numbers, rather than being deleted. Two is a budget I picked, not a number I measured. I have no case where I can show a third attempt would have been wasted, and at least one where the second attempt was itself the measurement that settled the question. What the rule actually bought was that stopping was pre-agreed, so it happened calmly and with the evidence intact instead of being argued about at the end of a long day.
The rule I would keep above all others is the two-key rule, written into GATES.md: a work stage may modify the solver or the acceptance criteria that judge it, never both. Seventeen task logs cite it explicitly, usually in their opening paragraph, usually as "no gate, tolerance or verdict logic was touched." It has exactly one recorded exception in the campaign, a gate change I pre-ratified in the brief myself, shipped in its own commit with no solver change beside it.
It exists because of an episode I am still slightly embarrassed by. There was a hardcoded exception in the harness, a timing-only allowance covering 2.4s to 2.6s of the take, with no measurement behind it. It touched three places, and in one it changed a verdict by subtraction. Worse, its guard was written as "not an arm" rather than "is a leg", so it was quietly widening the depth table for torso segments it was never scoped to cover. An amnesty task ripped it out and byte-diffed before against after on the same input: one harness check went from 1,937 failures to 1,960. Twenty-three frames it had been hiding, in exactly the windows I kept flagging by eye. GATES.md now reads "exceptions: none, ever, in any gate; named review items only." Every formerly-excepted frame is still reported, in a section whose own output says it has zero effect on the verdict above it.
The other standing rule is the byte-identical rollback proof. Any mechanism that ships behind a flag must be shown, by direct byte comparison of the baked GLB, to produce exactly the shipped bytes with the flag off, on all three bodies. That is a narrower guarantee than it sounds. It covers one baked artifact on the one take I own, and says nothing about a fourth body or a second take, neither of which exists to test against. The phrase "byte-identical" appears 187 times in the log. It is the reason a frozen negative costs nothing to keep.
Three rows in GATES.md were still marked NEEDS RATIFICATION when the campaign stopped. I would rather ship with that visible than quietly assumed.
The three failures that taught the most
An agent caught the orchestrator lying. The log entry closing the campaign stated that two branches had been merged into the trunk. A later agent, sent to build on top of that merge, opened its own log with a section titled "a repo finding that had to be fixed before any work could start." It had run git merge-base --is-ancestor, got a no, and grepped the trunk's solver for the three flag names the merged work would have introduced. Zero occurrences of any of them. The thirteen-crossing stack it had been sent to ship did not exist in the branch it had been sent to ship it from.
It merged the branches itself as its first commit, then found a second claim in the same entry describing a tool fix likewise absent from the code. That one mattered: the tool refused to burn detector verdicts onto a video when the detector file was legitimately clean, which meant medea, the one body sitting at zero crossings, could not be filmed at all.
This was catchable only because briefs told agents to trust code over narrative and verify the tree themselves. The log is evidence, not a status report, and it is worth keeping only if it can be audited against the thing it describes.
Three agents stalled the same way. Each backgrounded its own subprocess and then sat waiting on it, and went nowhere. It happened three separate times before I stopped treating it as bad luck and put it in the standing brief preamble. Any failure mode that recurs across independent agents is a brief defect, not an agent defect. Agents are disposable; the brief is the thing that persists.
The measurement path was nondeterministic and I trusted it a round longer than I should have. The crossing inventory was, for a while, taken from a live browser capture. Then a task measured the capture path against itself. Four independent captures of a byte-identical bake of the same body returned 3, 4, 5 and 5 detected crossing windows, with 0, 1, 2 and 2 between-frame events, and one window's peak depth reading 20.5, 20.6, 17.1 and 15.3mm. Nothing was broken. The detector deliberately fires on single frames, because a fast kick physically cannot sustain a crossing across consecutive samples, so whether a one-frame event is seen depends on where the capture's sampling phase lands in a real browser's animation loop.
Every inventory moved to solver-emitted scans that same day, and later task logs cite the rule by name. The surviving distinction is worth stating precisely: the offline bake path is deterministic and is held to true byte-identity, no exceptions. The live capture path cannot be, even in principle, so the honest claim available there is that a debug flag's contribution to frame-to-frame noise is the same order of magnitude as two baseline runs against each other. Two baselines of the same URL with zero code changes already diverge by up to 0.027 scene units at the hips. A flag that adds no more than that is doing nothing.
What a pile of measured negatives is worth
The visible score is modest. Nineteen detected leg crossings at campaign start, fifteen shipped, thirteen in a frozen stack one unfixed defect from shipping. On the whole inventory, legs plus arms, that is twenty-one down to seventeen. Contact fidelity came in at F1 .956 to .975, better than the source take's own baseline under the same measurement.
The invisible score is a directory of dead ends, each frozen behind a default-off flag with its numbers and its rollback proof intact. A grip-azimuth yield cap that made crossings worse at every strength tried. A per-frame side corridor, fully built and calibrated, killed by geometry. A topological repair pass that fixed zero of nineteen crossings and instead produced the three overlapping walls explaining why: six of nineteen sit on a limb the solver does not own, four have the hip itself inside the keep-out, and fourteen fall inside a span the solver had already recorded as beyond reach. Five knee fixes across three tasks, all negative, ending in a diagnosis sharp enough to close the family by measurement (one sign flip in 2,002 adjacent frame pairs, corpus-wide).
Every one narrowed the next brief. The freeze is what makes them cheap: nothing deleted, nothing shipped, nothing regressed, and each can be flipped back on with one environment variable once the thing blocking it is fixed. The file of dead ends is the map.
What I would do differently
Audit the data before commissioning fixes to the code. The tool that finally found the root cause of most of this reads a script file in seconds, with no bake and no browser, and it did not exist until day three.
Test coupled fixes as a stack, not one at a time. Piecewise, each fix inherits the other unfixed bugs as its acceptance baseline and dies on them. Revert-first isolation stays right for diagnosis; it was wrong for shipping decisions here.
Build the detector before the fix, calibrate it on defects a human has actually confirmed, and make the human grade the detector. Every fix attempted before its detector existed was wasted.
Distrust the convenient measurement path. The deterministic one was free and sitting right there the whole time.
Audit the gates themselves, not just compliance with them. Nearly every rule in this post is about running the process cleanly against the acceptance criteria, and those criteria were wrong more than once during this campaign: collision radii hardcoded far thinner than the mesh, a report ranking violations by key order instead of severity, an absolute gate that the source performer's own take could not pass. Seventeen task logs certifying that no gate was touched is worth nothing if the gate is measuring the wrong thing.
And keep the log adversarial. The one false claim that got into it was caught only because agents were told to check code rather than believe prose. Had my briefs said "the merge has landed, build on it," the campaign would have closed on a result that did not exist.